DynaTokens: Controlling Token Dynamics for Continual Video-Language Understanding

Toan Nguyen1, Yang Liu1, Celso De Melo2, Flora D. Salim1
1School of Computer Science and Engineering, University of New South Wales (UNSW Sydney), Australia
2DEVCOM Army Research Laboratory, USA
EMNLP 2026 ยท Main Conference
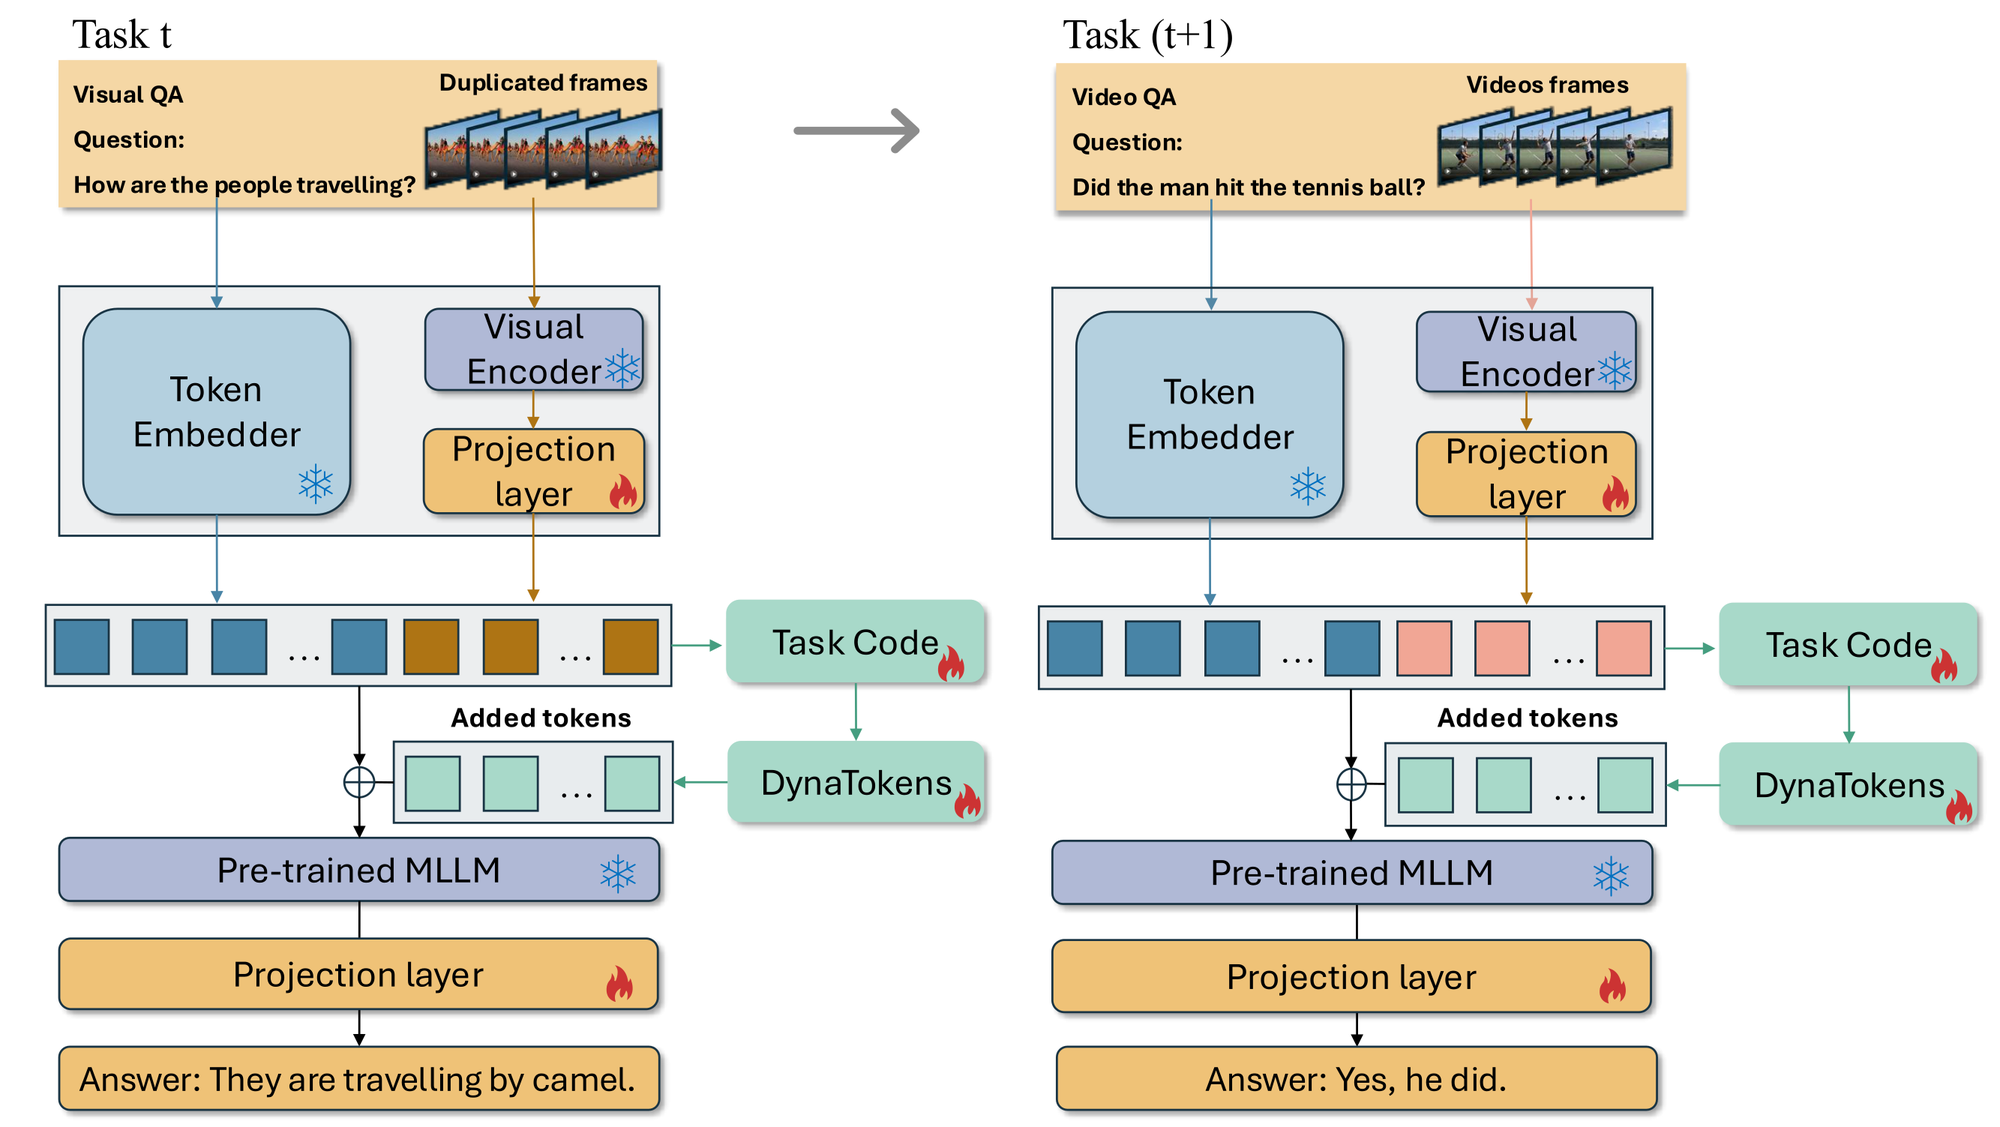
DynaTokens teaser

Continual adaptation with DynaTokens: a fixed-size token generator synthesises task-specific fine-tuning tokens on demand from a compact task code, for VideoQA and for cross-modal VisualQA โ†’ VideoQA transfer. โ„๏ธ frozen   ๐Ÿ”ฅ trainable.

๐Ÿš€ Summary of DynaTokens

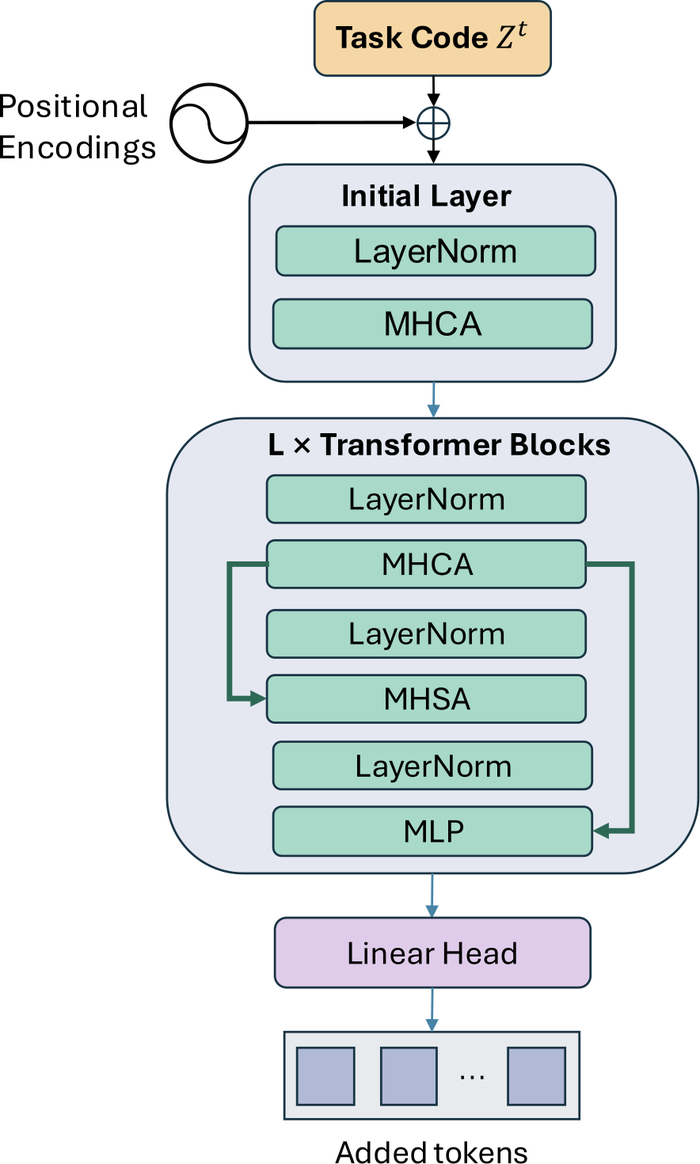
A hypernetwork that generates adapter prompts on demand for continual VideoQA on a frozen multimodal LLM (LLaMA-2-7B + CLIP ViT-L/14): each task is only a compact code, so memory stays flat as tasks accumulate.

๐Ÿ† New state of the art on continual VideoQA: 64.11 / 72.52 Acc and 4.76 / 9.76 forgetting on NExT-QA / DramaQA, and the best results on a 13-task NExT-QA โ†’ DramaQA stream and in zero-shot transfer.

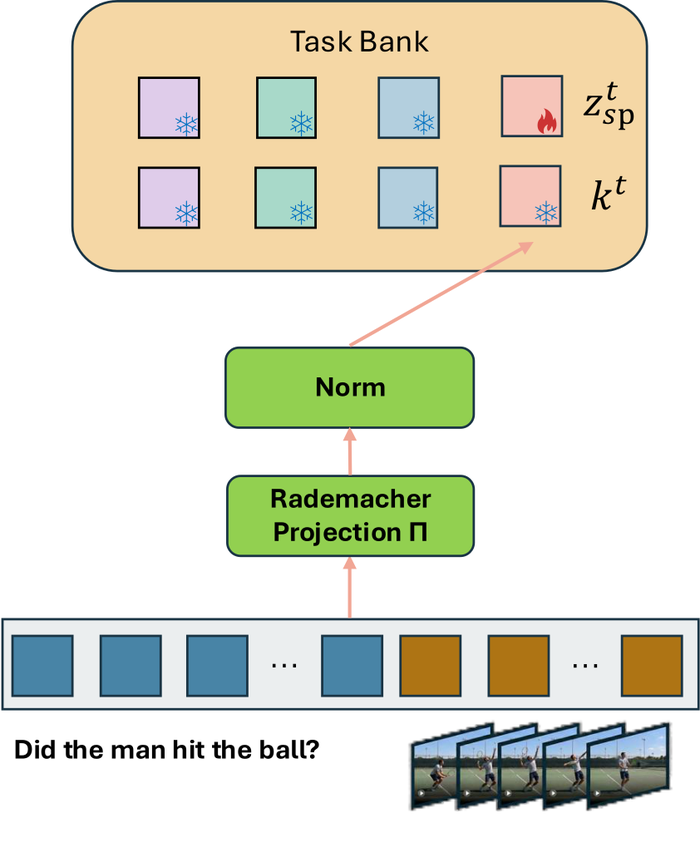
๐Ÿงญ Gradient-free routing: task keys come from frozen embeddings through a fixed random projection, so the router has no trainable parameters and cannot drift. No task id is needed at test time.

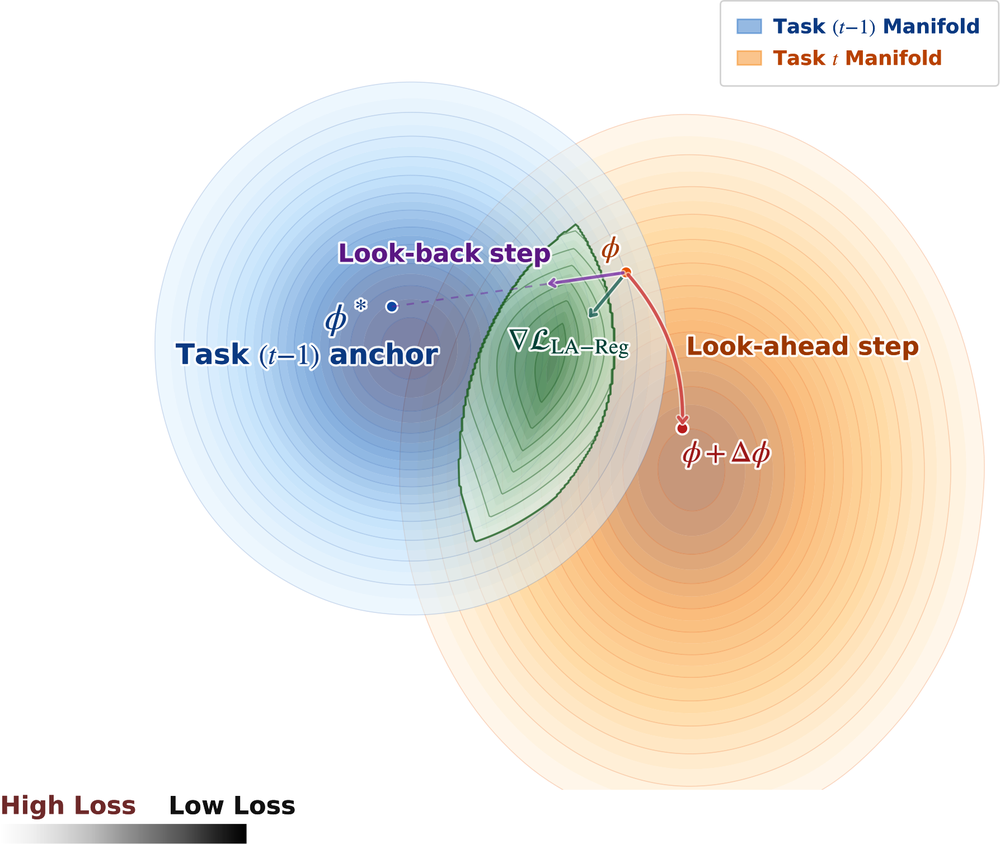
๐Ÿ”ญ LookAhead regularisation (LA-Reg): a meta-learning-inspired objective that looks ahead along the current-task update and anchors past-task prompt outputs, provably acting as a cross-task sharpness penalty (SAM-like) that favours flatter minima.

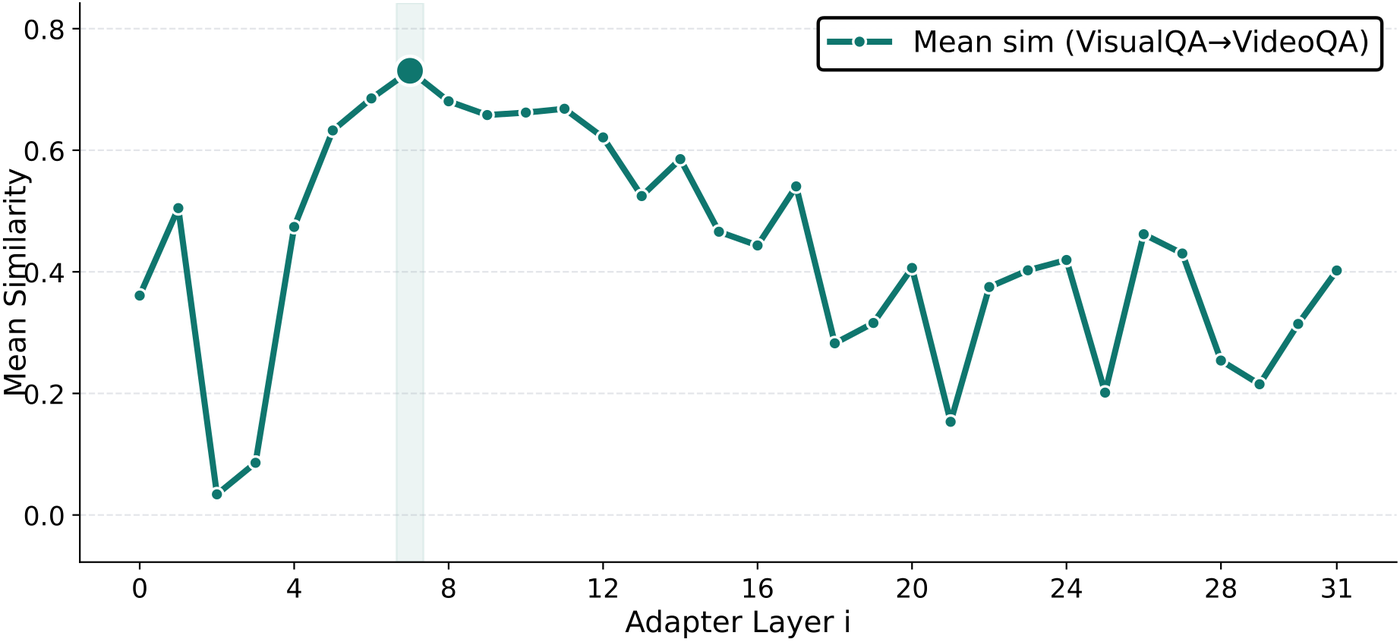
๐Ÿ–ผ๏ธโžก๏ธ๐ŸŽฌ A new ImageQA โ†’ VideoQA continual protocol (Visual7W โ†’ NExT-QA): DynaTokens stays robust where the strongest baseline degrades sharply.

+1.74
Acc over Bisecle
on NExT-QA
โ‰ˆ26 KB
storage per task,
constant along the stream
+6.65
Acc over Bisecle on the
13-task NExT-QA โ†’ DramaQA stream
0
trainable parameters
in the router

๐ŸŽฌ Live Demo: after 8 tasks, who still remembers?

Both models learned the same 8 question-type tasks sequentially on NExT-QA (same backbone, data and schedule). We now ask questions from tasks learned earlier in the stream. DynaTokens retrieves the task code from the question (no task id given) and synthesises that task's fine-tuning tokens on the fly. Pick a question, watch the clip, then reveal the answers.

The 10 uniformly sampled frames the model actually sees.

Task of this question:  ยท  Ground-truth answer is highlighted after reveal.

Bisecle (NeurIPS'25)

?

Press Reveal answers

DynaTokens (ours)

?

Press Reveal answers

๐Ÿ” Challenges in Continual VideoQA with Multimodal LLMs

โ€ข Plasticity vs. stability. Sharply shifting task distributions (e.g. different question types or video domains) make sequential prompt updates interfere and erode prior knowledge: catastrophic forgetting.

โ€ข Per-task prompts scale poorly. Storing a separate adapter prompt per task (ProgPrompt, ModalPrompt) preserves knowledge but memory grows with every task (โ‰ˆ5 MB per task on LLaMA-2-7B).

โ€ข Shared prompts conflict. Sharing prompt parameters (Bisecle, ColPro, L2P) is efficient but exposes the shared components to conflicting gradients under a small prompt budget.

โ€ข Routers drift. Learned routers must themselves be protected against forgetting; when task identity is hidden at test time, a drifting router silently sends samples to the wrong prompts.

DynaTokens addresses all four with one shared token generator, compact task codes and drift-free routing.


โœจ Results

Acc โ†‘: average top-1 accuracy over all tasks after the sequence  ยท  For โ†“: average forgetting (drop from each task's peak to its final accuracy)  ยท  best second best. All methods share the same frozen LLaMA-2-7B + CLIP ViT-L/14 backbone with 32 adapter layers.

๐ŸŽฌ Continual VideoQA on NExT-QA (8 tasks) and DramaQA (5 tasks)

MethodNExT-QADramaQA
Acc โ†‘For โ†“Acc โ†‘For โ†“
LLaMA-Adapter (ICLR'24)46.5813.8360.9924.39
L2P (CVPR'22)48.8212.2562.5020.67
DualPrompt (ECCV'22)50.6211.7465.8917.93
LAE (ICCV'23)49.3811.4765.8217.35
ProgPrompt (ICLR'23)53.9510.6967.9214.95
ColPro (EMNLP'24)55.147.4371.2412.64
DAM (WACV'25)53.889.9967.3715.19
Bisecle (NeurIPS'25)62.375.3471.4910.37
DynaTokens (ours)64.114.7672.529.76

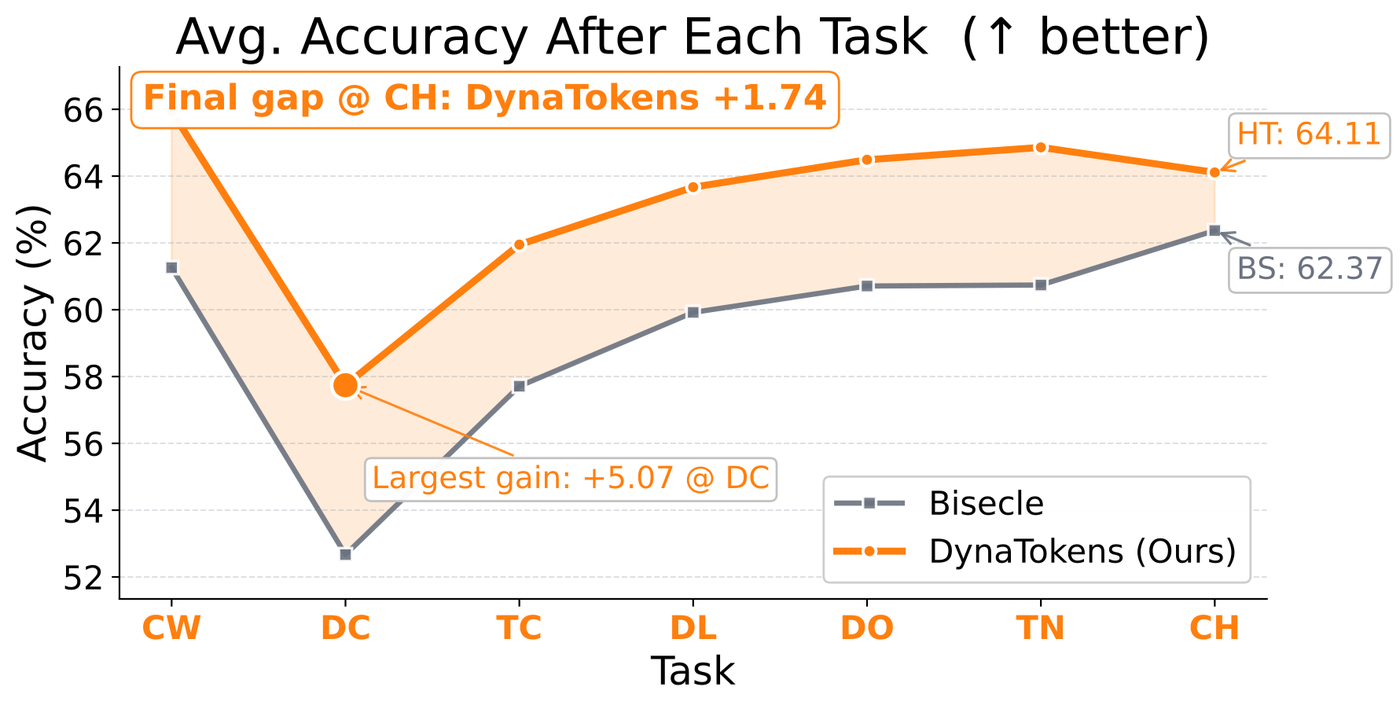
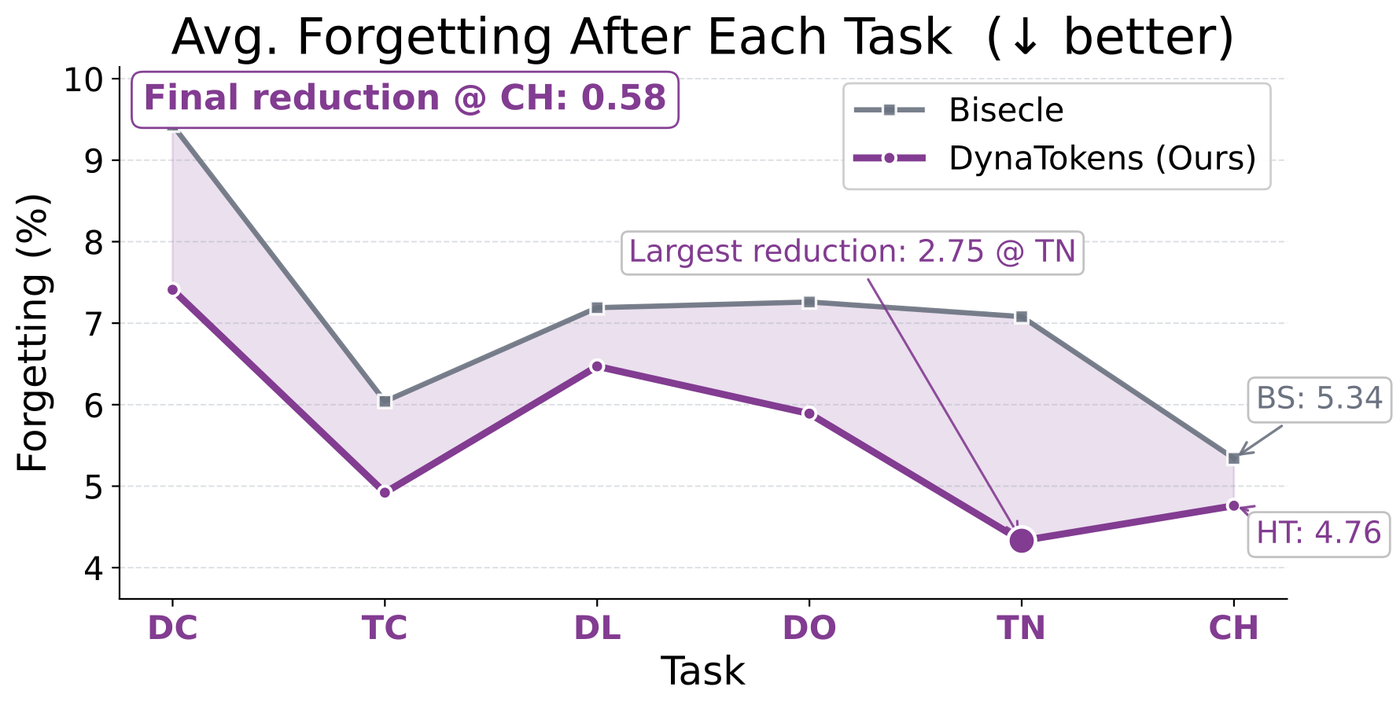
DynaTokens sets a new state of the art on both benchmarks: +1.74 Acc and โˆ’0.58 forgetting over Bisecle on NExT-QA, +1.03 Acc and โˆ’0.61 forgetting on DramaQA.

Accuracy and forgetting after every task (NExT-QA)

Average accuracy per task
Average forgetting per task

DynaTokens leads Bisecle throughout the sequence and the gap widens as tasks accumulate: the largest single-task gains are +5.07 Acc (DC) and โˆ’2.75 forgetting (TN). TP is excluded from the accuracy plot and TP-CW from the forgetting plot (forgetting starts at DC).


๐Ÿ” Ablations & Analysis

  • ๐Ÿ”ญ LA-Reg is the main driver of anti-forgetting: adding it alone lifts NExT-QA Acc from 21.28 to 62.12 and cuts forgetting by more than 3ร—.
  • ๐Ÿชœ More look-ahead steps help monotonically (54.54 โ†’ 62.30 โ†’ 63.92 โ†’ 64.11 Acc); the 1-step variant halves training time and is a practical default.
  • ๐Ÿ’พ Deployment cost stays flat: โ‰ˆ26 KB per task and inference latency within โ‰ˆ3% of the baselines.
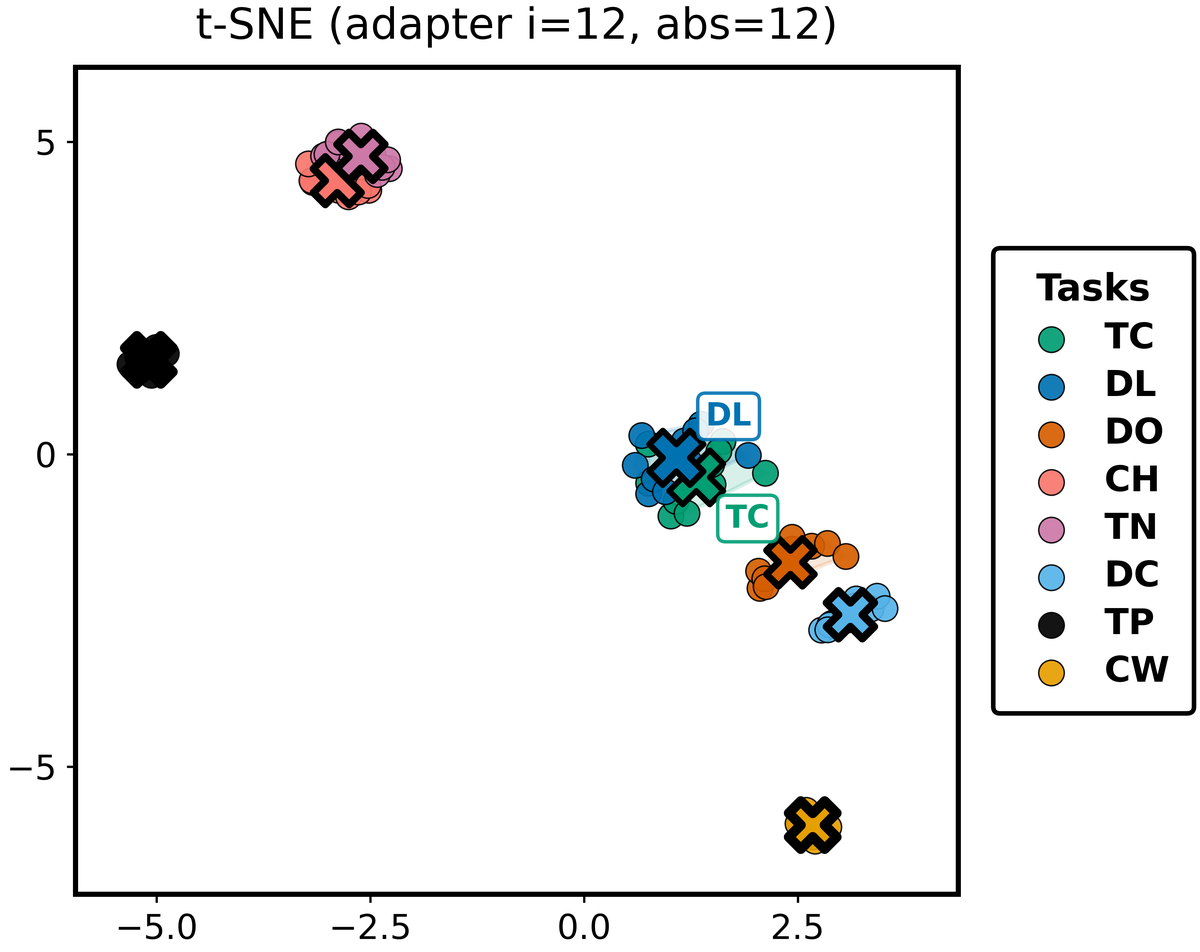
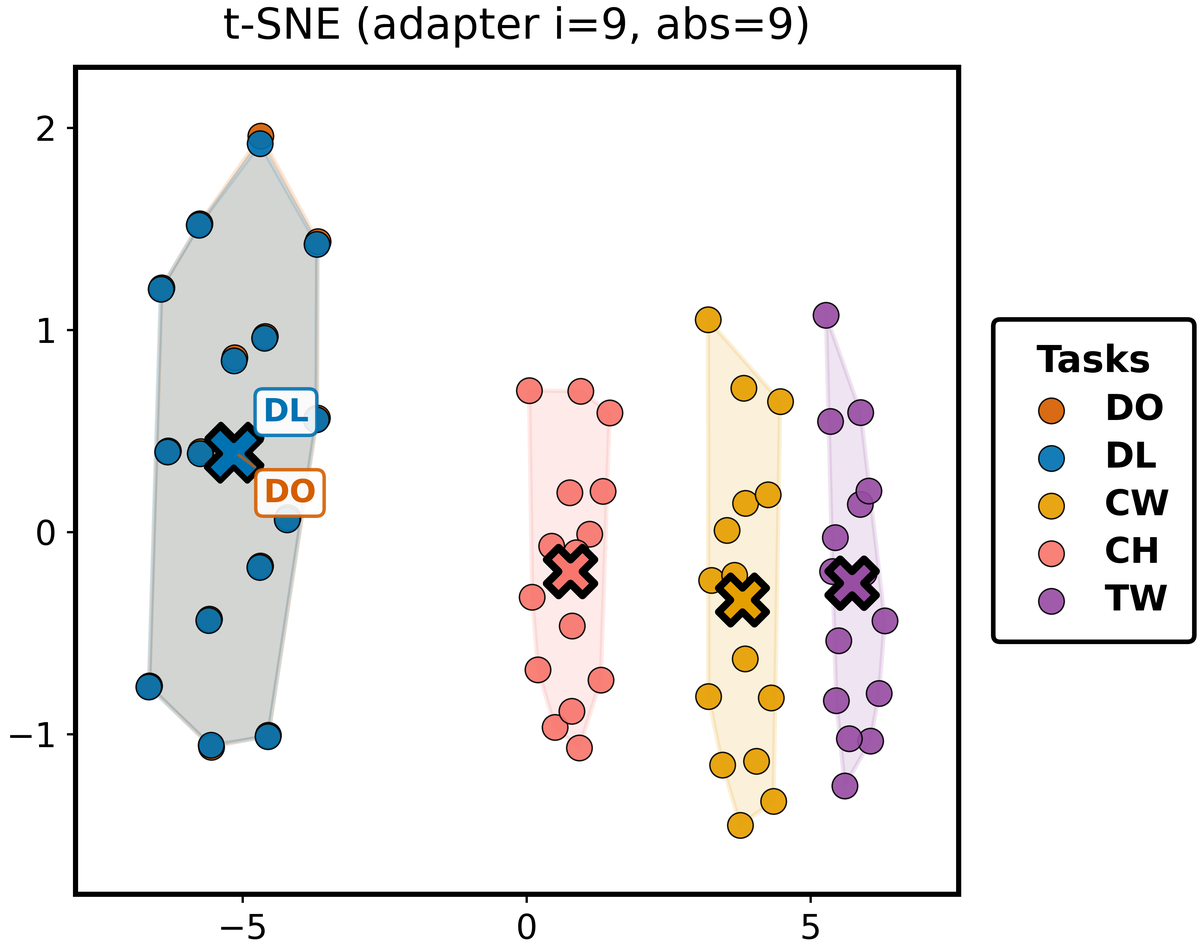
  • ๐Ÿงฉ Prompt tokens self-organise by reasoning skill rather than by the dataset's taxonomy, and clusters stay well separated after the whole stream.

๐Ÿงช Contribution of the loss terms (NExT-QA)

\( \mathcal{L}_{\text{LA-Reg}} \)\( \mathcal{L}_{\text{Inv}} \)\( \mathcal{L}_{\text{Aux}} \)Acc โ†‘For โ†“
โœ—โœ—โœ—21.2816.46
โœ—โœ—โœ“54.548.83
โœ“โœ—โœ—62.125.46
โœ“โœ“โœ—62.415.19
โœ“โœ—โœ“63.794.88
โœ“โœ“โœ“64.114.76

\( \mathcal{L}_{\text{Inv}} \): invariance term on \( z_{\mathrm{inv}} \); \( \mathcal{L}_{\text{Aux}} \): weighted VAQ + QAV auxiliary objectives. The three terms are complementary: the full objective is best on both metrics.


๐Ÿ’ป Code

Paper: arXiv:2603.06662. Training and evaluation code for NExT-QA, DramaQA, the 13-task stream and the Visual7W โ†’ NExT-QA protocol is available at github.com/cruiseresearchgroup/DynaTokens.

git clone https://github.com/cruiseresearchgroup/DynaTokens.git
cd DynaTokens
conda env create -f environment.yml && conda activate dynatokens
bash scripts/run_nextqa.sh      # continual NExT-QA (8 tasks)
bash scripts/run_dramaqa.sh     # continual DramaQA (5 tasks)

BibTeX

@inproceedings{nguyen2026dynatokens,
  title     = {DynaTokens: Controlling Token Dynamics for Continual Video-Language Understanding},
  author    = {Nguyen, Toan and Liu, Yang and De Melo, Celso and Salim, Flora D.},
  booktitle = {Proceedings of the 2026 Conference on Empirical Methods in Natural Language Processing (EMNLP)},
  year      = {2026}
}